Each policy controls the whole body and the neck of a Unitree G1, using only the onboard camera and proprioception.
Our team
*Equal contribution · Improbable AI Lab, MIT
Paper overview
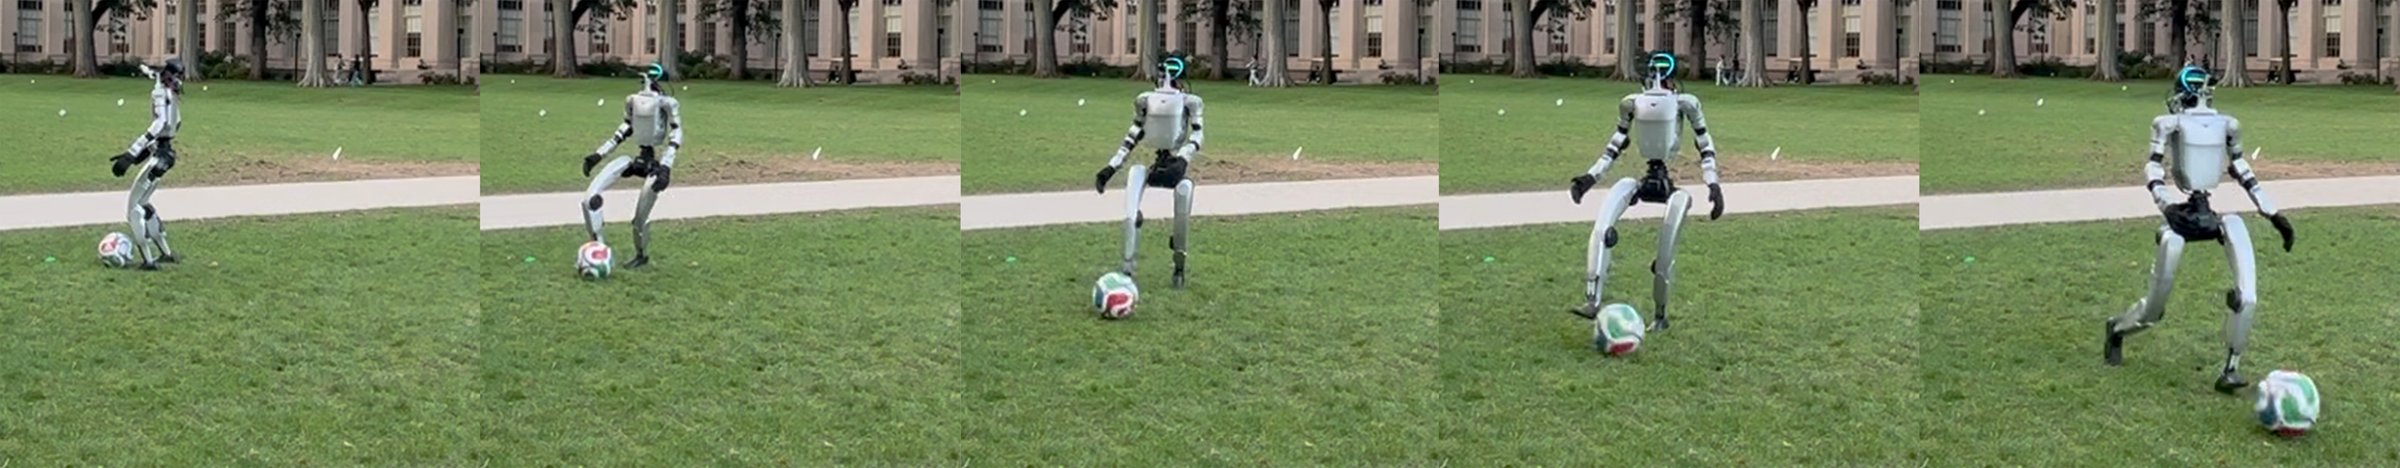
Joga is a full-stack system for humanoid dribbling, shooting, passing, and receiving. A torso-mounted actuated neck gives the robot active vision, and data-driven alignment of perception and dynamics preserves the speed and precision learned in simulation when the policies run on hardware.
Abstract
Humanoid robots can learn soccer skills through reinforcement learning in simulation, but inaccuracies in simulated perception and dynamics can limit speed and precision on hardware. Domain randomization paired with learned online adaptation can improve sim-to-real transfer, but specifying realistic perception and dynamics variations during training remains challenging. We introduce Joga (Joint Optimization of Gaze and Action), a full-stack system for humanoid dribbling, shooting, passing, and receiving. Rather than relying on hand-designed randomization, we learn a perception alignment model and a whole-body unsupervised actuator network from limited real-world hardware data to correct the nominal simulator. All skill policies train with modeled perception errors to improve foot-ball contact precision, and the dribbling policy is further finetuned in the actuator residual-augmented simulator to improve agility. On a Unitree G1, perception and dynamics alignment increase 135°-turn success from 3/5 to 5/5 trials, and it increases average ball speed over successful dribbling runs by 33% to 1.7 m/s, with an estimated peak of 2.3 m/s. The system also transitions directly from dribbling to passing and shooting and demonstrates single-touch receiving of a pass arriving at 5.2 m/s.
Real-world skills
Four agile soccer skills, all 31 actuators, onboard sensing only
Long runs
Minutes of dribbling without a reset
Raw footage with sound: four minutes on turf, three and a half minutes in strong wind, and a run on rough grass.
Stress tests in simulation
One run, conditions changing underneath it
The dribbling policy keeps the ball through slick ground, a 6° slope, a ball 2.5× heavier, 110 N shoves, the ball knocked off its line, a 30 N crosswind, and a 4 kg payload on the torso, all in one continuous run in MuJoCo.
Each condition is named on screen. Inset: the onboard camera view.
The problem
Small errors in sight and motion break precise foot-ball contact
Policies trained in simulation see a cleaner ball and a more ideal body than the real robot has. Broad domain randomization hides these gaps but makes the policy slow and conservative.
How can we preserve the speed, precision, and fluidity learned in simulation when a humanoid plays soccer in the real world?
The system
Joga: close both sides of the sensing-action loop
-
1
Active vision hardware
A custom torso-mounted 2-DoF neck carries an RGB camera for rapid, stable gaze changes during fast locomotion.
-
2
Perception alignment model
Learn the state-dependent bias, noise, and dropout of onboard ball detection from paired detector and motion-capture data.
-
3
Whole-body actuator network
Learn joint-position command corrections from 10 minutes of hardware dribbling, then finetune the dribbling policy in the corrected simulator.
-
4
Distributional skill chaining
Finetune passing and shooting from states visited during dribbling so skills hand off mid-stride.
A neck built for the sim-to-real gap
Two servos mounted directly on the torso, with no external linkages, gears, or bearings, so the neck is fast and needs no neck domain randomization.
The neck is open source, and our build guide covers the parts list, print settings, step-by-step assembly, wiring, and a URDF.
Build your own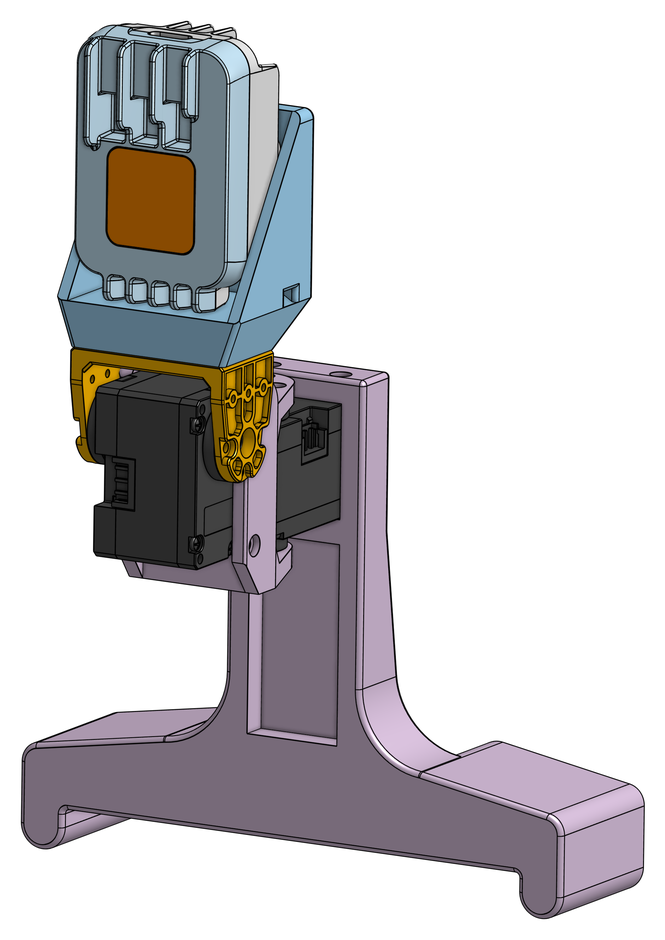
Active vision while dribbling toward the goal. Inset: the onboard camera on the neck, with the detected ball (green box) and the ball joystick command (orange arrow).
Perception alignment
Learn what the camera actually sees
The Perception Alignment Model (PAM) learns the bias, noise, and dropout of onboard ball detection from 10 minutes of paired detector and motion-capture data, then replaces perception randomization in training.
Dynamics alignment
A whole-body residual for agile dribbling
The Whole-Body Unsupervised Actuator Network (WB-UAN) corrects the simulator's joint-position targets using the state of the whole body, fit from 10 minutes of hardware dribbling with no torque or motion-capture labels. The dribbling policy is then finetuned in the corrected simulator.
Replaying recorded hardware commands in simulation: WB-UAN rollouts (teal) track the hardware reference (white) more closely than the simulator without a residual (orange).
Skill chaining
Strike from mid-stride, not from a standstill
Passing and shooting are finetuned from robot and ball states collected while dribbling, so control can switch skills mid-stride.
Switching from dribbling to shooting in simulation: a striking policy trained from random initial states (left) versus one finetuned with distributional skill chaining (right).
More on hardware
Receiving, ball skills, and playing with people
Questions & answers
Common questions
What does the name mean?
Joga stands for Joint Optimization of Gaze and Action: each policy controls the neck and the body together. It also nods to “joga bonito,” Portuguese for “play beautifully,” a soccer philosophy of creativity, joy, and flair.
Are the videos sped up? Who controls the robot?
No. All hardware videos play in real time (1×). A human operator joysticks the robot live, much like playing a video game: the joystick commands where the ball should go, and the policy decides how the whole body and neck move to get it there.

- D-pad: skill. ▲ walk · ▶ dribble · ▼ receive.
- Left stick. Walk velocity; while dribbling, the target ball velocity. Also aims passes and shots.
- Right stick. Turn.
- R2 (hold). Sprint.
- □ shoot.
- ✕ pass.
Why a custom torso-mounted neck?
The robot must keep the ball in view from long-range approaches down to close-range foot contact, including while accelerating and turning. A torso-mounted 2-DoF neck driven directly by two servos changes gaze quickly and reduces jitter, and avoiding external linkages, gears, and bearings limits the backlash and compliance that would otherwise need to be randomized in simulation.
Why model perception errors in bounding-box space?
The real pipeline goes image → detector box → pinhole back-projection. Modeling residuals on the box (center for bearing, log-size for range) and back-projecting reproduces that interface exactly, so a residual in box size maps directly to a relative depth error, just as it does on the robot.
How does PAM differ from distance-dependent noise models?
A linear baseline conditions only on range with affine per-axis moments and constant dropout. It captures the mean depth bias but not the motion- and pose-dependent structure, so it overestimates depth noise at close range and stays flat against ego-motion. PAM conditions jointly on ball geometry and robot motion and learns a nonlinear distribution over box errors and visibility.
How is WB-UAN different from Contact-UAN?
Contact-UAN learns joint-local corrections from each actuator's own tracking-error history. WB-UAN keeps Contact-UAN's contact-consistent replay and unsupervised fitting, but a single network sees absolute joint positions and commands across the whole body, so each joint's correction can depend on other joints. This better fits recorded hardware trajectories and yields faster, more controllable dribbling.
What runs on the robot at deployment?
Only the skill policies, the onboard ball detector, and proprioception. PAM and WB-UAN are simulator-side models used during training, and motion capture is used only to collect PAM training labels.